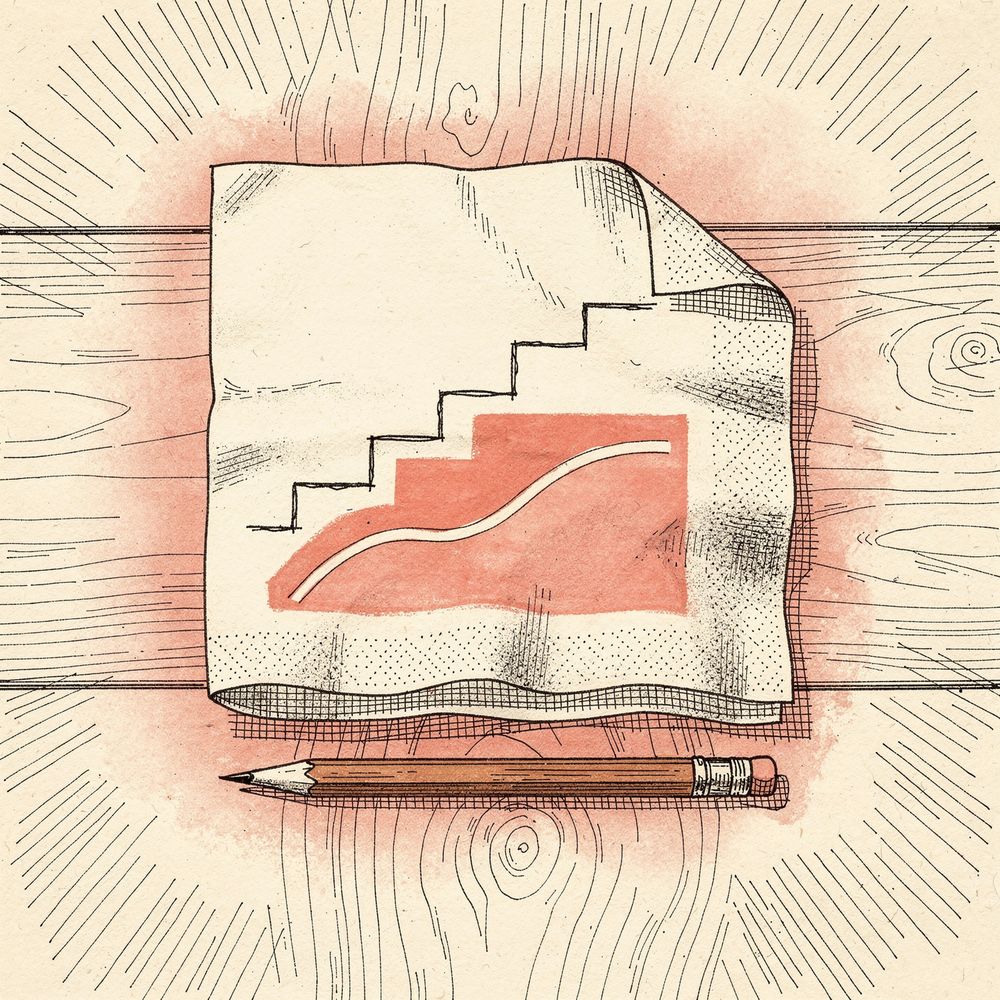
Why it's called that
Because none of it is precise, and pretending otherwise would be worse. These are approximations you could work out on a napkin: rough enough to argue with, specific enough to act on. There's no true arithmetic here. It's directionally how I think about getting things into the world.
The problem it solves is one every creative team has. A big idea shows up, gets scoped, and disappears into eight weeks of execution. Nothing reaches an audience until it's finished. And the first real signal about whether anyone wanted it arrives after all the money has been spent.
Do we have a shared understanding of what "good enough" means? And how do we stop over-polishing the things that turn out not to work?
The math that makes the case
Here's a real one. A benchmark report, eight weeks of work, projected at 47 MQLs a week once it's fully live in an interactive format.
Built the usual way, it goes live in week nine. Twelve-week quarter, four weeks of value: 188 MQLs.
Built in layers, the same eight weeks of work ships three times. A blog teaser with a download form goes live in week three at maybe a quarter of the effect. A PDF behind a basic form lands in week five at around 60%, and it's good enough to run paid against. The interactive page still arrives week nine at full strength.
341 MQLs against 188. Same total effort, same end state, an extra 153 in the same quarter, bought entirely by shipping earlier at lower fidelity.
Nobody can forecast that a teaser blog will run at 25% effectiveness. I made that up, and so will you. The precision is fake. What isn't fake is the shape: a staircase always encloses more area than a cliff. You don't need the estimates to be right for the conclusion to hold, which is exactly what makes it napkin math.
The lifecycle
Three moves, run continuously rather than as a project plan.
| Move | The question | What it looks like |
|---|---|---|
| Create | What's the smallest version of this idea that can exist? | Owned channels only: blog, social, email, podcast. Nothing that needs another team's roadmap. |
| Test | Does anyone actually want this? | Real audience, real numbers, before design or web are involved. |
| Iterate | Does this deserve more? | Heighten it into the bigger format, or kill it and take the week back. |
The owned-channel step is the part people skip, and it's the whole engine. Your blog and your social accounts are the only places you can ship something on Tuesday without asking permission. That makes them a proving ground, not a distribution channel. It's where an idea earns the right to consume somebody else's bandwidth.
Both directions
It runs down as well as up. Scaling down is taking a campaign nobody will fund and finding the version you can ship this week to prove it's worth funding. Scaling up is noticing that a throwaway post outperformed everything else that month and asking what it becomes at ten times the size.
A worked example of the second: comic-style images in social, each telling a story in a single panel. Posts perform, so the panels become a carousel. The carousel gets shared and downloaded, so it becomes a printed comic handed out at trade shows. Nobody would have approved the printed comic in week one. The data bought it.
What you front-load
Iterating fast only works if iterating is cheap. If every new cut means a new brief, a new argument, and a new round of approvals, the cadence dies in a month. So the front-loading is where the discipline actually lives.
The one thing worth doing first: write the argument once, at every length it will ever need.
Break the message into eight fragments and write each at three lengths. Long for post copy and landing pages, short for headlines and carousel cards, compressed for search and small display where one text element has to survive alone.
| Fragment | What it does |
|---|---|
| Tension | They recognize their own week in it |
| Claim | We take a position, flat and unhedged |
| Turn | The implication lands |
| Hero proof | It stops being opinion |
| Supporting proof | It wasn't a fluke |
| Stake | What it costs to be wrong |
| Position | Why it's us saying it |
| Ask | The exit, easy and small |
After that, building a placement is assembly. A designer picks fragments off a shelf instead of rewriting to fit. A social post is tension plus claim plus proof at long. A display banner is the claim at compressed. A carousel is six fragments at short, in order. The recipe references fragment names and lengths, never content, which means the same table works for every campaign you ever run.
Adjust the recipe, never the fragment. If a placement feels wrong, put a different fragment in that slot. Rewriting at the placement is the exact failure this exists to prevent. Do it thirteen times and you have thirteen slightly different arguments, none of them approved, and no way to tell whether a result was about the message or the rewrite.
Two fragments earn their keep more than the rest. Position is the only one that makes the ad yours rather than the category's; without it you're buying awareness for a topic, including for your competitors. And any fragment that can't survive at compressed length isn't a fragment. If the claim only works at 40 words, it's too complicated to run a campaign on. Finding that out while writing costs an hour. Finding it out during build costs a sprint.
Nobody opens with the tight set
A comedian doesn't write an hour and then perform it. They go up with note cards, half-formed, reading off the card and watching the room. Something gets a small laugh. Something dies. They go home, cut the dead bit, tighten the one that landed, and go up the next night with a slightly better version.
After enough nights there's a set. It flows, every line earns its place, and it sounds like it was written that way. It wasn't. It was found.
Ad testing is the same job. Your first placements are note cards. You're not looking for a standing ovation, you're looking for the small laugh: the click-through that's a little higher than the others, the line somebody quotes back to you, the message that gets a reply. Then you cut, tighten, and go up again.
The rough early set is the method, not a failure. A comedian who refuses to go up until the material is perfect never gets material. And you have to be in the room. Reading the numbers afterward isn't the same as watching where people leaned in, which is why the person making the work should be close to how it lands.
The metaphor breaks in one place, and the break is instructive. A comedian hears the laugh in real time, in the room, unmistakably. You get a number three days later, mixed with noise, arriving after you've already formed an opinion. That gap is exactly why the decision rule gets written before launch. It's the substitute for hearing the room.
How you read the result
Most creative testing amounts to building several things, launching them together, and interpreting whatever comes back. That produces a ranking, and a ranking isn't something you can build on. You know that ad beat this one, but not which of the four differences did the work. Next quarter you're guessing again with a bigger folder of assets.
Two things in a test are identical except for the single thing you're testing. Offer, audience, landing page, budget and dates all held. If two things changed, you learned nothing.
The second idea is that variables have an order. Wide ones first, because a narrow test run underneath a moving variable is unreadable. You can't learn which call to action works while the format beneath it is still changing.
| Order | The question | Read on |
|---|---|---|
| 1 · Campaign | Where should the money go? | Pipeline, cost per opportunity |
| 2 · Offer | What should we make more of? | CPL, lead-to-MQL rate |
| 3 · Format | How should we build it? | CTR, thumbstop |
| 4 · Creative | What should it look and sound like? | CTR, landing page conversion |
| 5 · CTA | What should the button say? | CTR |
You can only compare two things that share every level above them. A CTA comparison is valid inside one offer, one funnel stage, one format, one audience. "CTA X wins overall" is the most common way this gets broken, because the winning CTA is usually just the one that ran on the biggest budget at the top of the funnel.
Write the decision rule before you launch
Every test carries a hypothesis, the one variable, everything held constant, one primary metric, a minimum sample per arm, and what you'll do if A wins, if B wins, or if it's flat. If you can't write that last part, don't run the test. You're running it for the feeling of rigor, and the budget should go to one that would change your mind.
Three outcomes, all useful. Keep: one arm clearly ahead, lock the variable, retire the loser rather than rebuilding it for another audience as a consolation prize. Split: the result differs by audience or platform, so stop pooling that variable and assign it by segment, which is a finding rather than a failure. Flat: the variable isn't a lever, so decide on cost and move on.
One practical constraint worth knowing before you plan a backlog. At realistic budgets you can read large differences and not small ones. Person versus product, stat versus question, one message against another are all readable. Button colour, minor copy tweaks, small layout shifts are not readable without many multiples of typical spend. If you can't articulate why two arms would perform very differently, you're paying to watch a coin flip.
Design for function, not aesthetics.
Karl Blanks & Ben Jesson · Making Websites WinWhere the time goes
Running this way means protecting room for work that might not pay off, which is the first thing a quarterly target squeezes out. The split I use, deliberately lopsided:
| Type | Share of results | Share of time |
|---|---|---|
| Proven: established authority, already ranks and converts | 70% | 20% |
| Promising: early signs of working, worth refining | 20% | 50% |
| Experimental: unproven, and often weird | 10% | 30% |
Read the two columns against each other and the argument is right there. Proven content carries most of the number on a fifth of the effort, because optimizing something that already ranks is cheap. That efficiency is what funds the bottom row. Thirty percent of the team's time producing a tenth of the results looks indefensible on a spreadsheet, and it's the only line that produces next year's proven content.
What gets made at all
Napkin math tells you how to build. It doesn't tell you what deserves building, and without something to answer that, prioritization gets decided by whoever argued hardest in the meeting.
A scoring model I've adapted from Anton Rius, who calls the cost of that meeting the decision tax:
(Audience Value + Business Utility) × Impact Potential
Audience value and business utility both score one to five. Impact potential is a multiplier from one to three, covering how many teams could use it, how many formats it survives, and how long it stays true. Twenty-five and up is fast-tracked; under six goes in the backlog and mostly stays there.
The number isn't the point. The point is that it moves the conversation from "I think" to "this scores twelve, and we agreed twelve waits." You can argue with the score. You can't argue with it forever.
What it costs
Worth saying plainly, because this gets sold as free and it isn't.
- The first cycle is slower. Writing eight fragments at three lengths before anything ships feels like overhead, because on campaign one it is. It pays back on campaign three.
- Rough work goes out under your name. A teaser blog at 25% effectiveness is, by definition, not your best work. If the organization can't tolerate that, this framework won't survive contact with the first review cycle.
- Killing things has to be normal. The savings come from abandoning ideas early. That only works if abandoning something is a good outcome rather than a failed project someone has to explain.
- Efficiency isn't optional. The time for the experimental 30% comes from automating the parts that don't need judgment. Without that, the experimental row is the first thing cut.
When it breaks
When there's no front-loaded module set, so every iteration originates from scratch. When the same person makes the work and decides whether it won. When someone edits mid-flight to help a variant along. And when leadership treats a killed experiment as a failure. One of those conversations and the team stops proposing anything they aren't already sure about, which is the end of the whole thing.